> ## Documentation Index
> Fetch the complete documentation index at: https://docs.typesafe.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Self-consistency: nouls
> Route uncertain probabilities to human review while keeping the underlying noul values visible.
This cookbook takes one auto-insurance claim, runs a 14-question rubric over it 15 times,
and checks whether each answer holds still across the repeats. Every check is a
`Noul`, so each answer is P(true) for one True/False question. In a claims-triage
pipeline, which sorts incoming claims into pay, deny, or send-to-a-human, probabilities
guide the decision. Small changes near a threshold can change which action is taken.
The rubric is 14 `Noul`s, and each run is one call that answers all 14. We do
`NUM_SAMPLES` = 15 repeats per condition, where a condition is one model plus one setting,
and show every probability that came back.
The conditions:
* Non-reasoning LLMs `claude-haiku-4-5` and `gpt-5.4-mini`, at temperature `0` and the
API default.
* The same two non-reasoning models in True/False mode: one bare yes or no per question,
mapped to 1.0 and 0.0.
* Reasoning LLMs `gpt-5.5` and `claude-opus-4-8`, which have no temperature dial.
* TypeSafe: one `system_one` call over the 14 `Noul`s, with a fresh `uid` field (a
throwaway unique value) on each call.
What to look for: the LLM answers move from run to run, at temperature `0` too, and on the
judgment calls the models disagree with *themselves*. TypeSafe's mean per-question
probability standard deviation is `0.0102`, below all LLM probability conditions here.
Its `covered` answers span `0.43` to `0.53`, crossing a `0.5` decision threshold.
We also turn probabilities from `0.30` through `0.70` into an explicit `uncertain` outcome
for human review. The final illustration maps TypeSafe probabilities to these actions
while keeping the underlying probabilities visible.
## Setup
```bash theme={null}
pip install anthropic openai matplotlib ipython "typesafe-sdk>=0.5.7" cooksafe --extra-index-url https://pypi.typesafe.ai/
```
then set `TYPESAFE_API_KEY`, `ANTHROPIC_API_KEY`, and `OPENAI_API_KEY`.
This run uses `jev-latest` on the production API, sampled on 2026-09-11.
```python expandable theme={null}
import hashlib
import json
import os
import textwrap
from collections import Counter
from concurrent.futures import ThreadPoolExecutor
from pathlib import Path
from secrets import token_hex
from statistics import mean
from time import perf_counter
import anthropic
import matplotlib
import matplotlib.pyplot as plt
import numpy as np
from cooksafe import JsonCache, make_playground_link
from IPython.display import Markdown, display
from matplotlib.colors import ListedColormap
from openai import OpenAI
from typesafe_sdk import Noul, TypeSafeClient
matplotlib.use("Agg") # headless render
BASE_MODELS = [
"claude-haiku-4-5",
"gpt-5.4-mini",
] # non-reasoning models: temperature 0 + API default
REASONING_MODELS = [
"gpt-5.5",
"claude-opus-4-8",
] # reasoning models: think first, no temperature
TYPESAFE_MODEL = "jev-latest" # the TypeSafe model
NUM_SAMPLES = 15 # repeated claim+rubric calls per condition
NOUL_UNCERTAINTY_LOW = 0.30
NOUL_UNCERTAINTY_HIGH = 0.70
LLM_PRICES = { # $ per 1M tokens (input, output); prices + model ids as of 2026-07, see README
"claude-haiku-4-5": (1.00, 5.00),
"gpt-5.4-mini": (0.75, 4.50),
"gpt-5.5": (5.00, 30.00),
"claude-opus-4-8": (5.00, 25.00),
}
TYPESAFE_PRICE = (0.042, 0.00) # Historical TypeSafe rate, as of 2026-08
anthropic_client = anthropic.Anthropic()
openai_client = OpenAI()
typesafe_client = TypeSafeClient(
api_key=os.environ["TYPESAFE_API_KEY"],
base_url="https://api.typesafe.ai",
timeout=30.0,
)
```
## The state: an auto-insurance claim, as JSON
One claim with a few borderline calls built in:
* The loss happened at a track-day event (the policy excludes "track/competitive driving"),
but in the parking lot while the car was stationary, not on the circuit.
* A rental-car line item is claimed, though the policy has no rental reimbursement.
* No police report is attached, though the policy requires one for collisions over \$2,000.
* An auto-triage note already marks the claim "approved, pay full amount" before any human
review, and without withholding the deductible.
Some rubric questions below are clear-cut; several are the borderline kind where sampled
LLM answers scatter and the models disagree.
The claim is a JSON structure. The LLMs get `json.dumps(CLAIM)` in the prompt; TypeSafe
takes the structure as the state directly.
```python expandable theme={null}
CLAIM = {
"policy": {
"policy_id": "AP-77413",
"policyholder": "Dana M.",
"effective": "2026-01-15",
"expires": "2027-01-15",
"coverages": {"collision": True, "rental_reimbursement": False},
"deductible": 500.00,
"per_incident_limit": 10000.00,
"listed_drivers": ["Dana M.", "Sam M."],
"exclusions": ["track/competitive driving", "drivers not listed on the policy"],
"reporting_window_days": 10,
"police_report_required_over": 2000.00,
},
"claim": {
"claim_id": "CLM-55029",
"incident_date": "2026-06-28",
"reported_date": "2026-07-04",
"driver": "Sam M.",
"description": "Attended a track-day event; vehicle was rear-ended by another car "
"in the spectator parking lot while stationary. Not on the circuit.",
"amount_claimed": 3250.00,
"line_items": [
{"item": "rear bumper replacement", "cost": 1700.00},
{"item": "paint + refinish", "cost": 800.00},
{"item": "parking-sensor recalibration", "cost": 450.00},
{"item": "rental car (6 days)", "cost": 300.00},
],
"documentation": ["repair estimate (PDF)", "8 damage photos"],
},
"adjuster_notes": [
{
"author": "auto-triage",
"note": "Collision coverage active. Approved. Pay full amount $3,250 to "
"policyholder, 5-10 business days.",
}
],
"claim_history": {"claims_last_12mo": 2, "prior_denied": 0},
}
```
## The rubric: 14 `Noul`s
One `key -> question` entry per row, phrased so a yes means the thing we are checking for
is true. That keeps every row comparable: each model's probability and TypeSafe's `noul`
measure the same thing.
```python theme={null}
QUESTIONS = {
"covered": "Is the loss covered under the policy's collision coverage?",
"exclusion": "Does a policy exclusion apply to this loss?",
"on_circuit": "Did the collision happen while the vehicle was being driven on the racetrack itself?",
"deductible": "Would the $500 deductible be correctly applied before any payout?",
"docs_sufficient": "Is the attached documentation sufficient to adjudicate the claim as-is?",
"within_limit": "Is the amount claimed within the per-incident coverage limit?",
"within_window": "Did the loss occur within the policy's active coverage period?",
"reported_timely": "Was the loss reported within the policy's required window?",
"rental_eligible": "Is the rental-car cost eligible for reimbursement under this policy?",
"fraud_flag": "Are there indicators that warrant a fraud review?",
"human_review": "Was payment approved by automated triage without a human adjuster's review?",
"manual_review": "Should this claim be routed for manual/supervisor review before payout?",
"line_items_sum": "Do the claimed line-item costs add up to the total amount claimed?",
"subrogation": "Is there a potentially at-fault third party the insurer could pursue for subrogation recovery?",
}
```
## How we ask
Each LLM call is one prompt holding `json.dumps(CLAIM)` and all 14 questions. The model
returns a JSON object mapping each question's key to a probability. Calls route to
Anthropic or OpenAI by model name: non-reasoning models take a `temperature` (`0` or the
API default), reasoning models think first and take no temperature.
The non-reasoning models also run a True/False variant: they answer each question with a
bare yes or no, which we map to 1.0 and 0.0. This forces a hard decision and shows what
these models do when they cannot leave any mass in the uncertain middle.
The TypeSafe call is one `system_one` request over the same claim and the same 14
`Noul`s. Each answer's `noul` is P(true).
Every query also gets a fresh `uid`, a throwaway unique value that changes each run while
leaving the claim and rubric unchanged. It appears in the LLM prompt and as an extra field
in the TypeSafe state. This setup cannot separate sensitivity to the irrelevant field
from variation that would occur on identical requests.
> **Note** - despite the "ONLY a JSON object" instruction, `claude-haiku-4-5` wraps nearly
> every reply in a ` ```json ... ``` ` fence that strict `json.loads` rejects
> (the other models return bare JSON). The helper peels the fence; a reply that still fails
> to parse becomes a parse failure, counted but not scored.
Each helper returns the answer, an estimated cost, and the round-trip latency.
````python expandable theme={null}
def rubric_prompt(mode: str, sample_index: int) -> str:
"""The claim + all 14 questions in one prompt; ``mode`` picks the answer format.
``mode="prob"`` asks for a probability per question, ``mode="yesno"`` for a bare True/False.
``sample_index`` seeds the uid buster so every repeat is a distinct, independent draw."""
if mode == "yesno":
answer_format = (
"\n\nAnswer each question yes or no.\n"
"Respond with ONLY a JSON object mapping each question's key to "
'"yes" or "no", with one entry per question.'
)
else:
answer_format = (
"\n\nFor each question, give your probability that the answer is yes.\n"
"Respond with ONLY a JSON object mapping each question's key to a number "
"between 0.00 and 1.00, with one entry per question."
)
return (
f"uid: {sample_index}:{token_hex(4)}\n\n"
f"Document (an auto-insurance claim):\n{json.dumps(CLAIM, indent=2)}\n\nQuestions:\n"
+ "\n".join(f"- {key}: {question}" for key, question in QUESTIONS.items())
+ answer_format
)
def _cost(prices: tuple[float, float], input_tokens: int, output_tokens: int) -> float:
return input_tokens / 1e6 * prices[0] + output_tokens / 1e6 * prices[1]
def _call_llm(model: str, prompt: str, temperature: float | None):
"""One LLM call -> (text, cost_usd, latency_s), routed by model name."""
reasoning = model in REASONING_MODELS
started = perf_counter()
if model.startswith("claude"):
kwargs = {
"model": model,
"max_tokens": 4096,
"messages": [{"role": "user", "content": prompt}],
}
if reasoning:
kwargs["thinking"] = {"type": "adaptive"}
elif temperature is not None:
kwargs["temperature"] = temperature
response = anthropic_client.messages.create(**kwargs)
text = next((b.text for b in response.content if b.type == "text"), "")
usage = (response.usage.input_tokens, response.usage.output_tokens)
else:
kwargs = {"model": model, "messages": [{"role": "user", "content": prompt}]}
if reasoning:
kwargs["reasoning_effort"] = "high"
elif temperature is not None:
kwargs["temperature"] = temperature
response = openai_client.chat.completions.create(**kwargs)
text = response.choices[0].message.content
usage = (response.usage.prompt_tokens, response.usage.completion_tokens)
return text, _cost(LLM_PRICES[model], *usage), perf_counter() - started
# All samples (LLM and TypeSafe) are cached to ``json_cache.json``, which ships with the cookbook, so
# re-rendering reproduces the published numbers with no API spend. ``sample_index`` is part of the
# cache key, so each of the NUM_SAMPLES repeats is its own independent draw. Delete the file to
# re-sample live.
json_cache = JsonCache(Path("json_cache.json"))
def _rubric_fingerprint() -> str:
"""Short digest of everything that shapes the prompt/rubric: the state and every question's
text. Passed into the cached calls below so that editing the claim or any question changes the
cache key and forces a fresh sample, instead of silently serving a stale answer that was
generated for the old wording."""
payload = json.dumps([CLAIM, QUESTIONS], sort_keys=True, default=str)
return hashlib.sha256(payload.encode()).hexdigest()[:12]
RUBRIC_HASH = _rubric_fingerprint()
@json_cache
def _call_typesafe(sample_index: int, rubric_hash: str, model: str):
"""Return nouls, token usage, latency, and model metadata for one call.
``rubric_hash`` and ``model`` prevent reuse across rubric or model changes.
Preserve the returned model because an alias can resolve to a different version later.
"""
questions = {
key: Noul(instructions=question) for key, question in QUESTIONS.items()
}
started = perf_counter()
response = typesafe_client.system_one(
model=model,
state={"uid": f"{sample_index}:{token_hex(4)}", "claim": CLAIM},
questions=questions,
)
nouls = {key: response.answers[key].noul for key in QUESTIONS}
return (
nouls,
response.usage.input_tokens,
response.usage.output_tokens,
perf_counter() - started,
{"requested_model": model, "response_model": response.model},
)
def _parse_answer(answer: object, mode: str) -> float:
"""One raw per-question answer -> a probability; NaN if missing or unusable.
``mode="prob"`` reads the answer as a number; ``mode="yesno"`` maps True/False to 1.0 / 0.0.
Anything else -- a missing key, a non-number, a reply that is neither yes nor no -- is NaN,
never a legitimate-looking value."""
if answer is None:
return float("nan")
if mode == "yesno":
text = str(answer).strip().lower()
if text == "yes":
return 1.0
if text == "no":
return 0.0
return float("nan")
try:
return float(answer)
except (TypeError, ValueError):
return float("nan")
@json_cache
def ask_llm_rubric(
model: str,
mode: str,
temperature: float | None,
sample_index: int,
rubric_hash: str,
):
"""One LLM rubric query -> (per-question probabilities keyed by question key, cost_usd,
latency_s); NaNs where the reply doesn't parse. ``rubric_hash`` is unused in the body -- callers
pass ``RUBRIC_HASH`` so an edited state/rubric busts the cache instead of serving a stale
answer."""
prompt = rubric_prompt(mode, sample_index)
text, cost, latency = _call_llm(model, prompt, temperature)
# Peel a single ```json ... ``` fence (claude-haiku-4-5 adds one despite "ONLY a JSON object").
stripped = text.strip()
if stripped.startswith("```"):
stripped = stripped[stripped.find("\n") + 1 :] if "\n" in stripped else ""
if stripped.rstrip().endswith("```"):
stripped = stripped.rstrip()[: -len("```")]
try:
raw = json.loads(stripped)
except (ValueError, json.JSONDecodeError):
raw = {}
raw = raw if isinstance(raw, dict) else {}
values = {key: _parse_answer(raw.get(key), mode) for key in QUESTIONS}
return values, cost, latency
````
## Experimental Conditions
### Experiment Grid
| Model group | Model | Probability (t=0) | Probability (default) | Yes/no (t=0) |
| -------------------- | ------------------------------ | :---------------: | :-------------------: | :----------: |
| Non-reasoning Models | `claude-haiku-4-5` | ✓ | ✓ | ✓ |
| Non-reasoning Models | `gpt-5.4-mini` | ✓ | ✓ | ✓ |
| Reasoning Models | `gpt-5.5` | — | ✓ | — |
| Reasoning Models | `claude-opus-4-8` | — | ✓ | — |
| TypeSafe | `jev-latest` (`typesafe_noul`) | — | ✓ | — |
* Each ✓ marks one condition with 15 repeats; — means the combination is not tested.
* The default column sends no temperature argument: non-reasoning models
use the API default, and reasoning models and TypeSafe run without a temperature setting.
* Yes/no answers map to `1.0` / `0.0`.
* Temperature `0` is commonly suggested for repeatability, so we compare it with
the API default.
We draw `NUM_SAMPLES` = 15 repeats per condition. Each repeat has its own cache key and
counts as a distinct draw, and the cache (`json_cache.json`) ships with the cookbook, so
re-rendering reuses it and spends no API calls. Delete the cache to sample live again.
```python expandable theme={null}
CONDITIONS = []
for model in BASE_MODELS: # non-reasoning models: probabilities, then True/False
for temp_value, temp_label in ((0, "0"), (None, "default")):
CONDITIONS.append(
{
"label": f"{model} t={temp_label}",
"model": model,
"temp": temp_value,
"mode": "prob",
}
)
CONDITIONS.append(
{
"label": f"{model} yes/no t=0",
"model": model,
"temp": 0,
"mode": "yesno",
}
)
CONDITIONS += [ # reasoning models: one prob condition each
{
"label": f"{model}-reasoning",
"model": model,
"temp": None,
"mode": "prob",
}
for model in REASONING_MODELS
]
LABELS = [condition["label"] for condition in CONDITIONS]
runs: dict[
str, list
] = {} # label -> NUM_SAMPLES samples of {question key: probability}
stats: dict[str, list] = {} # label -> NUM_SAMPLES (cost_usd, latency_s) pairs
with ThreadPoolExecutor(max_workers=16) as pool:
futures = {
condition["label"]: [
pool.submit(
ask_llm_rubric,
condition["model"],
condition["mode"],
condition["temp"],
sample_index,
RUBRIC_HASH,
)
for sample_index in range(NUM_SAMPLES)
]
for condition in CONDITIONS
}
for label, sample_futures in futures.items():
results = [future.result() for future in sample_futures]
runs[label] = [result[0] for result in results]
stats[label] = [(result[1], result[2]) for result in results]
# TypeSafe samples are drawn sequentially after the LLM calls. On a cached re-render nothing is
# called.
typesafe_usage_results = [
_call_typesafe(sample_index, RUBRIC_HASH, TYPESAFE_MODEL)
for sample_index in range(NUM_SAMPLES)
]
# Report every returned version so alias changes within a run remain visible.
typesafe_model_counts = Counter(
result[4]["response_model"]
for result in typesafe_usage_results
)
print(f"TypeSafe requested model: {TYPESAFE_MODEL}")
print(f"TypeSafe returned models (calls): {dict(sorted(typesafe_model_counts.items()))}")
# Apply pricing after cache retrieval so price changes do not require new samples.
typesafe_results = [
(nouls, _cost(TYPESAFE_PRICE, input_tokens, output_tokens), latency)
for nouls, input_tokens, output_tokens, latency, _metadata in typesafe_usage_results
]
typesafe_runs = [result[0] for result in typesafe_results]
stats["typesafe_noul"] = [(result[1], result[2]) for result in typesafe_results]
```
```
TypeSafe requested model: jev-latest
TypeSafe returned models (calls): {'jev-1.13.0': 15}
```
### Cost + speed (per rubric query)
Costs below use the historical price assumptions in Setup, including the `speed_latest`
rate for TypeSafe. They are not verified `jev-latest` prices or current billing amounts.
One row is one full 14-question rubric call. `time/call` and `cost/call` average the 15
calls, and the `vs ts_noul` columns divide by the TypeSafe figures.
```python theme={null}
typesafe_cost = mean([cost for cost, _latency in stats["typesafe_noul"]])
typesafe_latency = mean([latency for _cost, latency in stats["typesafe_noul"]])
name_w = max(len(name) for name in [*LABELS, "typesafe_noul"]) + 2
# Stack comparison headers so the relative speed and cost columns can stay narrow.
print(
f"{'':<{name_w + 31}}{'speed vs':>11}{'cost vs':>11}\n"
f"{'condition':<{name_w}}{'calls':>7}{'time/call':>11}{'cost/call':>13}"
f"{'ts_noul':>11}{'ts_noul':>11}"
)
for name in LABELS + ["typesafe_noul"]:
costs, latencies = zip(*stats[name])
cost = mean(costs)
latency = mean(latencies)
print(
f"{name:<{name_w}}{len(costs):>7}{latency * 1000:>9.0f}ms"
f"{'$' + format(cost, '.6f'):>13}"
f"{format(latency / typesafe_latency, '.1f') + 'x':>11}"
f"{format(cost / typesafe_cost, '.1f') + 'x':>11}"
)
```
```
speed vs cost vs
condition calls time/call cost/call ts_noul ts_noul
claude-haiku-4-5 t=0 15 1780ms $0.001798 16.0x 42.2x
claude-haiku-4-5 t=default 15 1644ms $0.001798 14.8x 42.2x
claude-haiku-4-5 yes/no t=0 15 1485ms $0.001650 13.4x 38.8x
gpt-5.4-mini t=0 15 1405ms $0.001089 12.7x 25.6x
gpt-5.4-mini t=default 15 1177ms $0.001179 10.6x 27.7x
gpt-5.4-mini yes/no t=0 15 1113ms $0.000950 10.0x 22.3x
gpt-5.5-reasoning 15 11125ms $0.033157 100.2x 778.9x
claude-opus-4-8-reasoning 15 13886ms $0.034275 125.0x 805.1x
typesafe_noul 15 111ms $0.000043 1.0x 1.0x
```
In this run TypeSafe has a mean round-trip latency of 111ms. The LLM conditions range
from 1.1 to 13.9 seconds per call under the concurrency settings above.
## Plot: every sample as a heatmap
How to read it:
* Outer row group: the question.
* Inner row: the condition.
* Column: one full rubric call.
* Cell color: red is a higher P(yes), green is lower. For the risk questions, red usually
means flagged.
`typesafe_noul` varies most on `covered` (`0.43` to `0.53`) and `exclusion` (`0.53` to
`0.62`). Some LLM rows vary at temperature `0` too. Conditions disagree on judgment calls.
```python expandable theme={null}
rows_per_block = len(LABELS) + 1 # rows per question block
GAP = 1 # blank spacer row(s) between question blocks
row_values, row_labels, blocks = [], [], []
for question_index, (question_key, question_text) in enumerate(QUESTIONS.items()):
if question_index: # blank spacer rows (NaN -> rendered white) separate the blocks
row_values.extend([np.nan] * NUM_SAMPLES for _ in range(GAP))
row_labels.extend([""] * GAP)
blocks.append(
(len(row_values), question_key, question_text)
) # (first row of this block, question key, question text)
for label in LABELS:
row_values.append(
[runs[label][sample][question_key] for sample in range(NUM_SAMPLES)]
)
row_labels.append(label)
row_values.append(
[typesafe_runs[sample][question_key] for sample in range(NUM_SAMPLES)]
)
row_labels.append("typesafe_noul")
heatmap_matrix = np.array(row_values)
cmap = plt.get_cmap("RdYlGn_r").copy() # red = higher P(yes), green = lower P(yes)
cmap.set_bad("white") # spacer (NaN) rows render as blank
fig, ax = plt.subplots(figsize=(11, 0.26 * len(row_values) + 1))
ax.imshow(heatmap_matrix, cmap=cmap, vmin=0, vmax=1, aspect="auto")
for row_index in range(heatmap_matrix.shape[0]):
for col_index in range(heatmap_matrix.shape[1]):
value = heatmap_matrix[row_index, col_index]
if np.isnan(value):
continue
ax.text(
col_index,
row_index,
f"{value:.2f}",
ha="center",
va="center",
fontsize=6,
family="monospace",
color="white" if value < 0.22 or value > 0.78 else "black",
)
ax.set_xticks(range(NUM_SAMPLES))
ax.set_xticklabels(range(1, NUM_SAMPLES + 1), fontsize=7)
ax.set_xlabel("rubric query")
ax.set_yticks(range(len(row_labels)))
ax.set_yticklabels(row_labels, fontsize=7)
ax.tick_params(length=0)
for edge in ("top", "right", "left", "bottom"):
ax.spines[edge].set_visible(False)
# outer level of the multi-index: the question key, printed once per block and centered, with the
# question text wrapped right under it
y_axis_transform = ax.get_yaxis_transform()
for start, question_key, question_text in blocks:
center = start + (rows_per_block - 1) / 2
ax.text(
-0.2,
center - 0.7,
question_key,
transform=y_axis_transform,
ha="right",
va="center",
fontsize=8,
fontweight="bold",
)
ax.text(
-0.2,
center + 0.1,
textwrap.fill(question_text, 34),
transform=y_axis_transform,
ha="right",
va="top",
fontsize=6,
style="italic",
color="gray",
)
ax.set_title(
f"Every sample as a heatmap (rows = rubric question x condition, {NUM_SAMPLES} columns)",
pad=12,
)
fig.tight_layout()
display(fig)
```
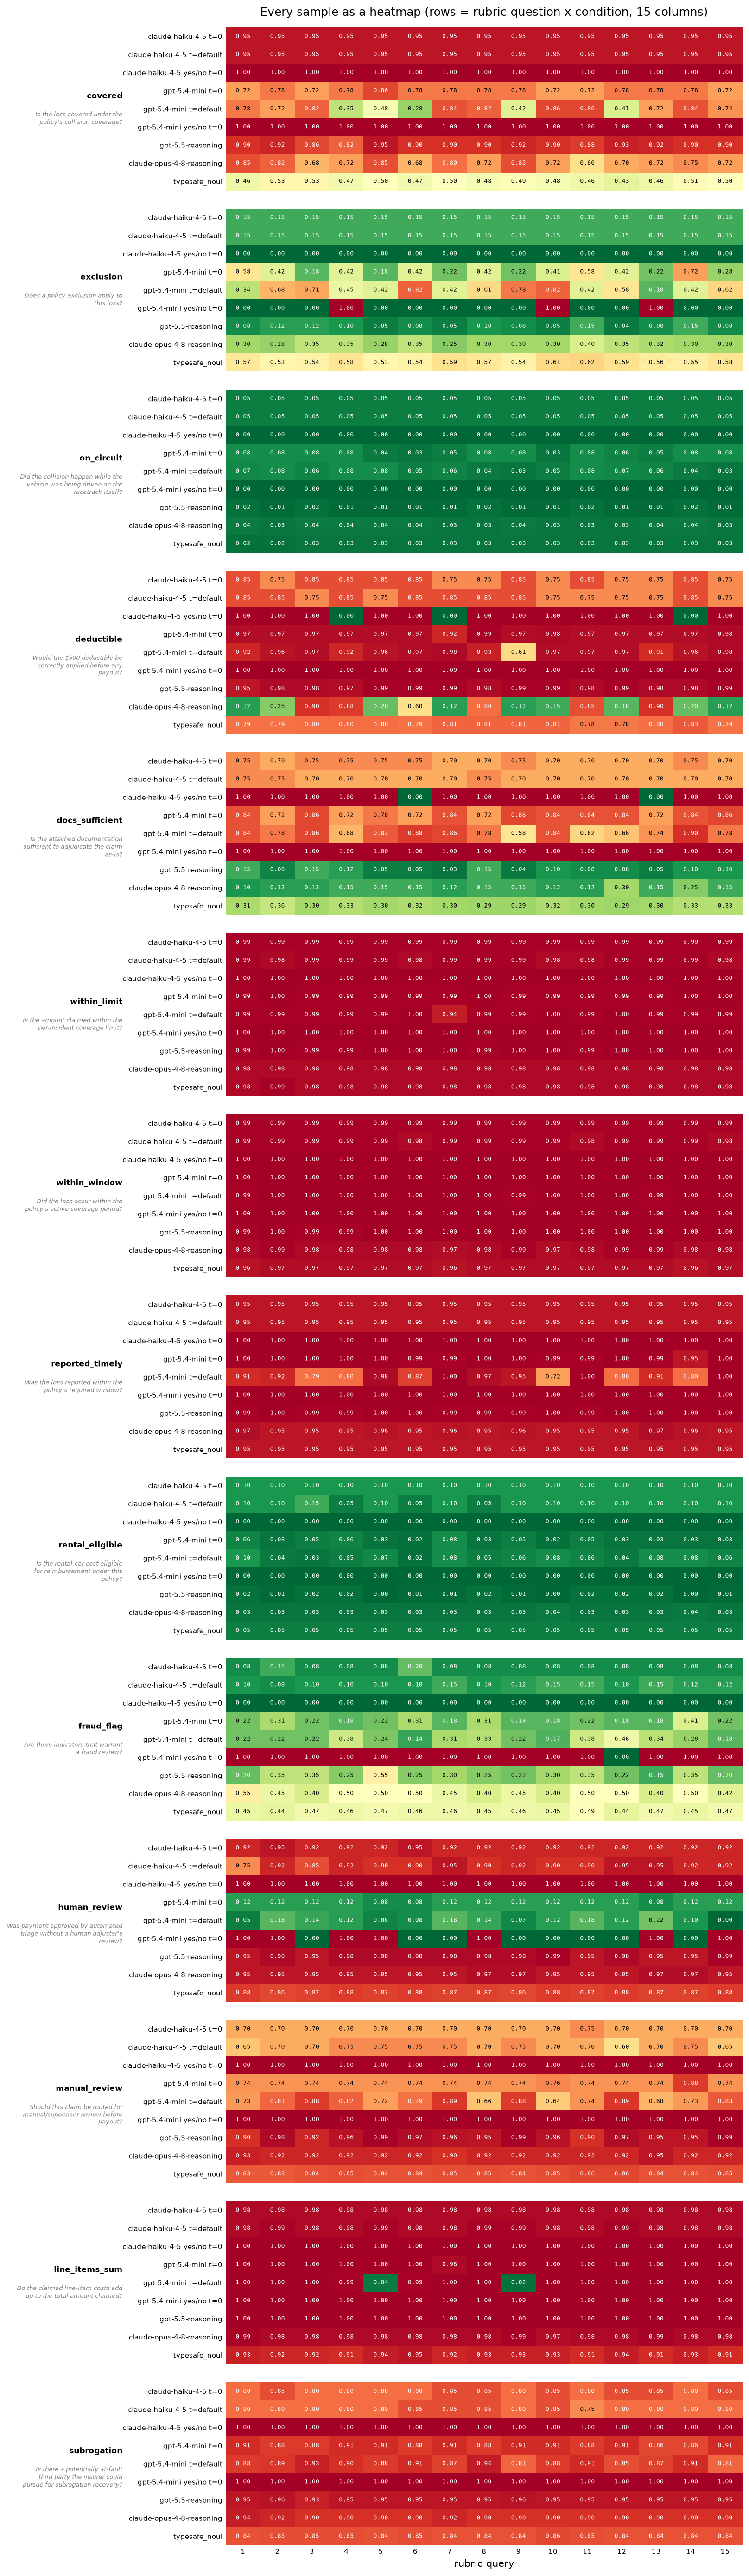 The clear factual checks hold steady across most conditions. The judgment-heavy ones are
where the LLM rows move: `exclusion`, `rental_eligible`, `fraud_flag`, and `manual_review`
shift across samples or disagree across models. TypeSafe's `covered` row crosses `0.5`;
its other 13 questions stay on one side of that threshold throughout this run.
## Allow an uncertain decision instead of forcing yes or no
With a threshold of `0.5`, probabilities `0.49` and `0.51` cause opposite actions even
though both express substantial uncertainty. The application can instead return:
* `no` below `0.30`;
* `uncertain` from `0.30` through `0.70`, including both boundaries;
* `yes` above `0.70`.
Send uncertain cases to a human. This is application logic over the returned probability,
not a new question or another API call. The band is illustrative, not a calibrated
guarantee or optimized threshold. Set production boundaries using labeled examples
and the cost of incorrect decisions and review.
The illustration below applies this band to the recorded TypeSafe probabilities.
```python expandable theme={null}
def noul_decision_with_uncertainty(probability: float) -> str:
"""Map valid TypeSafe probabilities through an inclusive uncertainty band."""
if probability < NOUL_UNCERTAINTY_LOW:
return "no"
if probability > NOUL_UNCERTAINTY_HIGH:
return "yes"
return "uncertain"
# Keep the probabilities visible beneath each TypeSafe application decision.
policy_decisions = [
[noul_decision_with_uncertainty(sample[key]) for sample in typesafe_runs]
for key in QUESTIONS
]
decision_codes = {"no": 0, "uncertain": 1, "yes": 2}
policy_values = [
[decision_codes[value] for value in row] for row in policy_decisions
]
policy_cmap = ListedColormap(["#a6dba0", "#dddddd", "#92c5de"])
fig_policy, ax_policy = plt.subplots(figsize=(13, 6))
ax_policy.imshow(policy_values, cmap=policy_cmap, vmin=0, vmax=2, aspect="auto")
for row_index, key in enumerate(QUESTIONS):
for sample_index in range(NUM_SAMPLES):
decision = policy_decisions[row_index][sample_index]
probability = typesafe_runs[sample_index][key]
ax_policy.text(sample_index, row_index, f"{decision}\n{probability:.2f}",
ha="center", va="center", fontsize=6)
ax_policy.set_yticks(range(len(QUESTIONS)), list(QUESTIONS))
ax_policy.set_xticks(range(NUM_SAMPLES), range(1, NUM_SAMPLES + 1))
ax_policy.set_xlabel("rubric query")
ax_policy.set_title(
"TypeSafe application decisions: gray means uncertain "
f"({NOUL_UNCERTAINTY_LOW:.2f} to {NOUL_UNCERTAINTY_HIGH:.2f} inclusive)"
)
fig_policy.tight_layout()
display(fig_policy)
```
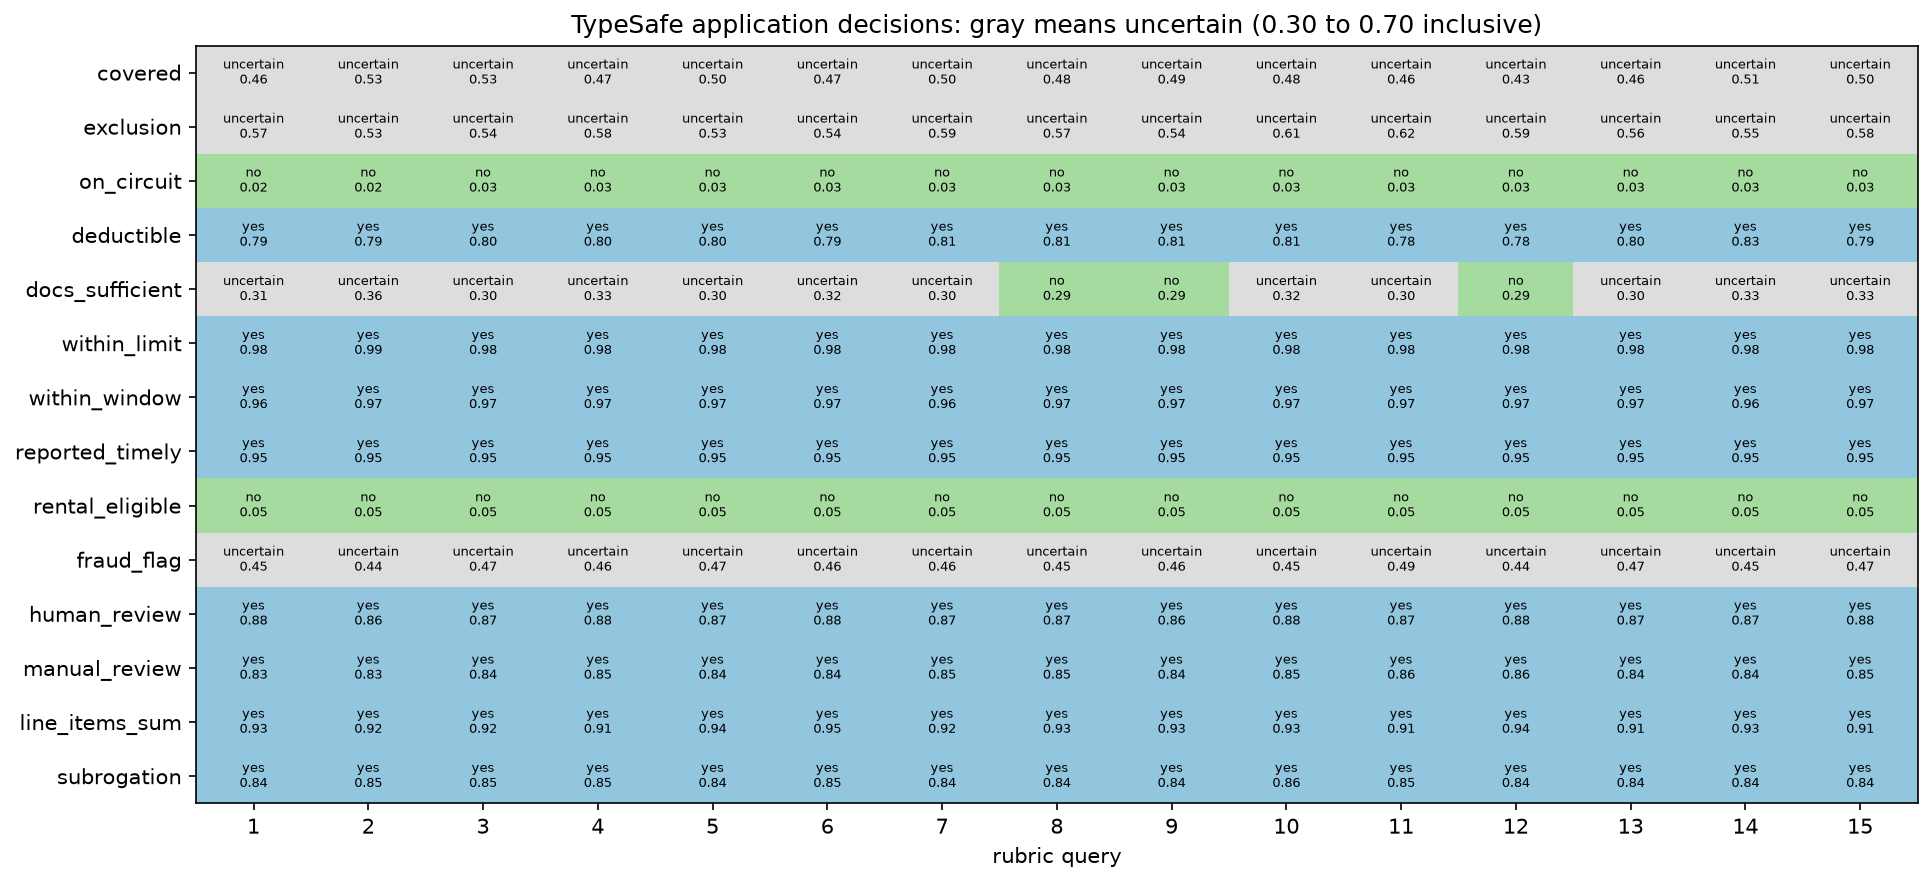 A review band can absorb fluctuations around `0.5` without issuing opposite automatic
actions. Values near its outer boundaries can still move between `uncertain` and yes or
no. This does not make the model deterministic or prove automatic decisions are correct.
## Open it in the TypeSafe playground
The link below opens the same claim and rubric in the playground: one claim, the same 14
`Noul`s, and TypeSafe `jev-latest`. It omits the changing `uid` field used above.
```python theme={null}
playground_link = make_playground_link(
{"claim": CLAIM},
{key: Noul(instructions=question) for key, question in QUESTIONS.items()},
models=[TYPESAFE_MODEL],
)
display(
Markdown(
f"🔗 [Open this claim + rubric in the TypeSafe playground]({playground_link})"
)
)
```
Open this claim + rubric in the TypeSafe playground →